A photo can travel surprisingly far from where it was first published. It may be reposted on social media, copied into a blog post, cropped for a forum, saved and uploaded again, or shared without the original caption.
By the time you encounter it, the photographer, location, date, and original webpage may be completely missing.
Finding the original source is not always possible, but a systematic search can often take you much closer than simply looking at the first result returned by an image search engine.
Here is a practical workflow for tracing a photo back through the web.
Step 1: Examine the Entire Image Before Searching
Start with the photograph itself.
Look beyond the main subject and note anything that could become a search clue: watermarks, usernames, logos, signs, storefronts, event banners, distinctive buildings, uniforms, product names, or text printed on clothing.
Also consider how the image appears to have been edited.
Is it unusually narrow? Does part of a watermark appear to have been cropped out? Are there borders or text that look like they were added later?
These details can help you recognize earlier versions when they appear in search results.
Step 2: Check the Information That Came With the Photo
Before uploading the image anywhere, return to the place where you found it.
A webpage may contain a caption, photo credit, publication date, author’s name, or link to another source. A social post may tag another account or mention where the photograph was taken.
Even the filename can occasionally provide a clue.
Save anything useful before moving on. Once an image has been downloaded, screenshotted, or forwarded, some of that surrounding context can easily disappear.
Step 3: Run a Reverse Image Search
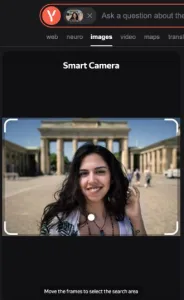
Next, upload the complete photograph to a reverse-image search engine.
For this workflow, Yandex Images is one option worth testing. Start with the full image rather than immediately cropping it. This gives the search engine access to the subject and the surrounding visual information.
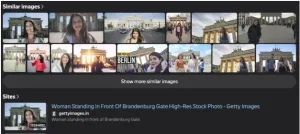
Review the results for pages containing the same image and for closely related versions.
The first result is not necessarily the original source. A popular repost can rank more prominently than a page that published the photograph years earlier.
Your objective at this stage is therefore to collect candidate sources, not immediately select a winner.
Step 4: Search Different Parts of the Image
If the full photograph produces weak results, change the search input.
Crop around distinctive elements individually. A logo, building, sign, artwork, product, or piece of text may be easier to trace than the complete scene.
If the image contains a visible watermark or username, search that separately as text.
You can also search exact phrases appearing in the photograph. Put distinctive wording inside quotation marks and combine it with other clues such as a location, event, organization, or approximate year.
This turns one visual search into several independent search paths.
Step 5: Look for Earlier and Better Versions
Once you begin finding copies, compare them carefully.
An earlier version may have a larger resolution, different crop, intact watermark, original caption, or additional visual information that disappeared from later reposts.
Publication dates are useful, but treat them carefully. A page’s displayed date may reflect an update rather than the first time the image appeared there.
Instead of relying on a single date, compare several signals: publication information, page context, image dimensions, credits, captions, and links between websites.
A higher-resolution or less-cropped image can also provide new clues for another search.
Step 6: Follow Credits Instead of Stopping at Reposts
Finding the same photograph on another website does not necessarily mean you have found its source.
Check the surrounding text for phrases such as Photo by, Image credit, Courtesy of, or Source.
If a news article credits a photographer or agency, search the photographer’s name together with details from the image. If a blog links to another website as its source, follow that link and continue backwards.
Think of the process as tracing a chain:
repost → credited source → earlier publication → possible original
The goal is to move backward rather than stopping at the first duplicate.
Step 7: Use Web Archives When a Source Has Disappeared
Sometimes a search result points to a page that no longer exists.
In that situation, a web archive can help determine what the page looked like previously. The Internet Archive’s Wayback Machine allows users to enter a URL and view archived versions of webpages when captures are available.
The Internet Archive explains how the Wayback Machine works and how archived URLs can be searched by date.
This can be particularly useful when an old article, portfolio page, or blog post appears to have hosted the photograph before newer copies appeared elsewhere.
An archived page still does not automatically prove that it was the first publication, but it can help reconstruct an otherwise broken source trail.
Step 8: Change Methods When the Photo Is Really About a Person
Sometimes the search changes halfway through.
You may begin by trying to find where a photograph was published, but realize that what you actually need is the identity or social profile associated with the person shown in it.
Traditional reverse-image search and face search solve different parts of that problem. Reverse-image tools are useful for locating copies and visually related versions of an image. Face-search tools can provide another route when the same person appears in completely different photographs.
If that becomes the objective, comparing the best face search for social media accounts can help you choose an appropriate search method rather than continuing to look only for copies of the original file.
Any possible facial match should still be treated as a lead rather than proof of identity.
Step 9: Verify the Source You Think You Found
Before calling a page the original source, ask what actually supports that conclusion.
Does it have the earliest credible publication date you found? Is there a photographer credit? Does the image appear in a larger or uncropped form? Does the page provide contextual information that later reposts copied?
Also look for evidence pointing in the opposite direction.
An article may explicitly credit another website. A photographer’s portfolio may show that the image predates the page you found. An older archived version may reveal a source that no longer appears in current search results.
Finding an early copy is easier than proving that you found the first copy.
Step 10: Know When “Original” Cannot Be Established
Not every image has a traceable online origin.
The original page may have been deleted before it was archived. The photograph may have first circulated through a private message or closed community. Search engines may not have indexed the earliest page at all.
In those cases, use precise language.
Instead of saying, “This is the original source,” it may be more accurate to say, “This is the earliest source I could verify.”
The same caution applies if the investigation shifts toward a person. Even the best face search for social media accounts can produce possible matches rather than definitive identification.
Trace the Photo, Not Just the Search Results
Finding the source of a photograph is usually a process of working backward.
Start with the image and its surrounding context. Search the complete photo, isolate useful details, compare different versions, follow credits, and use archived pages when the trail goes cold.
Most importantly, distinguish between the earliest source you found and a genuinely verified original.
A reverse-image result can start the investigation. Establishing where a photograph actually came from requires comparing the evidence behind those results.